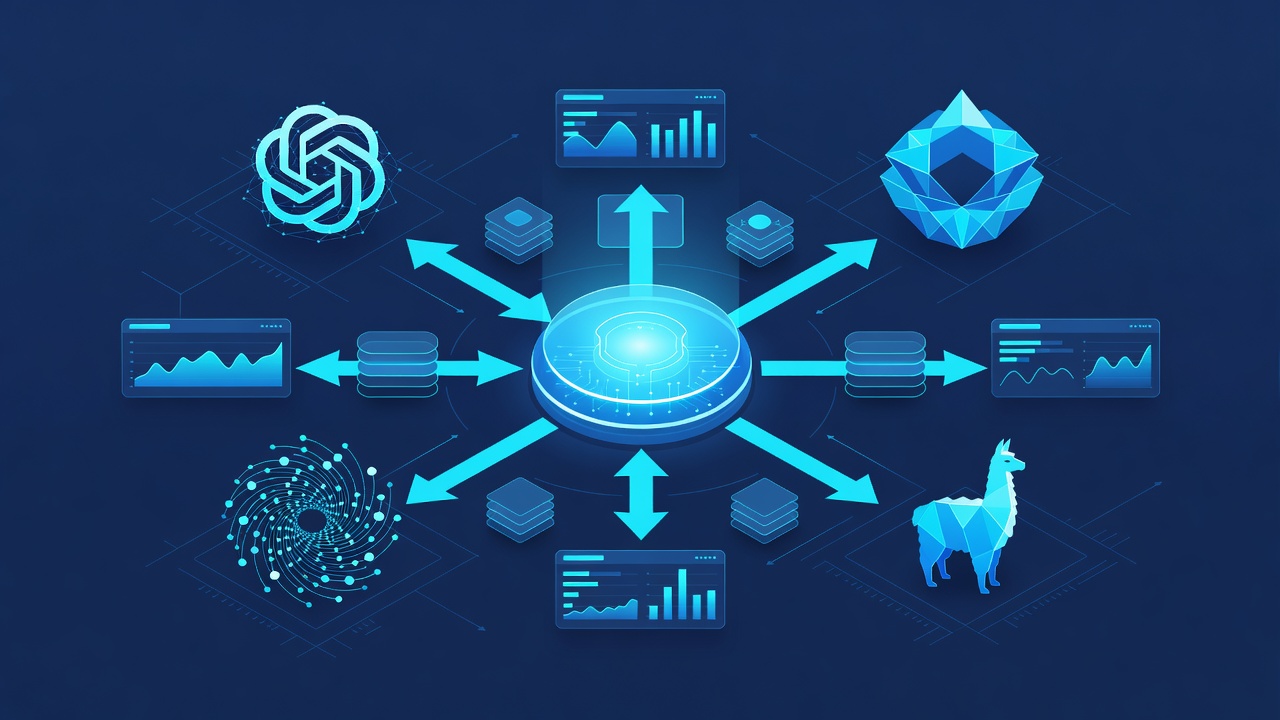
LiteLLM Proxy Architecture
LiteLLM provides both a Python SDK and a standalone proxy server that translates calls to the OpenAI client format into provider-specific requests. The proxy runs as a FastAPI application exposing /chat/completions, /embeddings and /images/generations endpoints. Version 1.52.0 added native support for over 100 providers including OpenAI, Anthropic, Cohere, Mistral, Groq, Together AI, Fireworks, Azure, Vertex AI, and local servers via Ollama or vLLM.
When a request arrives, the proxy performs three steps before forwarding: authentication against virtual keys, application of model-specific mapping rules, and execution of pre-call hooks. Responses flow through post-call hooks for caching, logging and spend tracking. This architecture adds a network hop but enables centralized controls impossible with direct SDK usage.
Running the Proxy in Production
Install with pip install 'litellm[proxy]'==1.52.0. Start the server using a configuration file rather than command-line flags for maintainability. A minimal config.yaml looks like this:
model_list:
  - model_name: gpt-4o
    litellm_params:
      model: openai/gpt-4o
      api_key: os.environ/OPENAI_API_KEY
  - model_name: claude-3-opus
    litellm_params:
      model: anthropic/claude-3-opus-20240229
      api_key: os.environ/ANTHROPIC_API_KEY
  - model_name: mistral-large
    litellm_params:
      model: mistral/mistral-large-latest
      api_key: os.environ/MISTRAL_API_KEY

general_settings:
  master_key: sk-1234
  database_url: postgresql://user:pass@localhost/litellm
Launch with litellm --config config.yaml --port 4000. The proxy registers models under friendly names so client code never changes when swapping providers. Database storage tracks spend per key and per team. For high availability, run multiple replicas behind a load balancer; each replica connects to the same PostgreSQL instance for shared state.
Virtual Keys and Budget Controls
Virtual keys replace raw provider keys in client applications. Create a key with curl -X POST http://localhost:4000/key/generate -H "Authorization: Bearer sk-1234" -d '{"models": ["gpt-4o"], "max_budget": 10.0}'. The returned key carries metadata including remaining budget, RPM limits and allowed models.
When a request arrives with the virtual key, the proxy decrements the remaining budget atomically in the database before forwarding the call. If the call would exceed the budget, it returns HTTP 429 immediately. This pattern centralizes cost governance for teams or customer tenants without modifying application code. Team budgets aggregate across all keys belonging to a team ID, enabling SaaS platforms to enforce per-customer spend caps.
Intelligent Routing and Fallback Patterns
Routing rules live in the config under router_settings. A common pattern routes between cost and quality tiers:
router_settings:
  routing_strategy: latency-based-routing
  fallbacks:
    - gpt-4o: [claude-3-sonnet, mistral-large]
    - claude-3-opus: [gpt-4o, together_ai/mixtral]
  retry_policy:
    - model: gpt-4o
      max_retries: 2
      retry_after: 0.5
The proxy measures latency per model over a sliding window and prefers the fastest healthy provider for each model group. When a provider returns a 5xx or times out, the fallback list is tried in order. This pattern improved availability from 98.2% to 99.94% for one production deployment by automatically switching between OpenAI and Anthropic during regional outages.
Model groups allow the same friendly name to map to different providers based on region or load. For example, embedding-model can route to text-embedding-3-small or voyage-2 depending on current pricing or rate limit headroom.
Response Caching Strategies
LiteLLM supports three cache backends: in-memory (for single process), Redis, and semantic cache. Enable Redis caching with:
cache:
  type: redis
  host: localhost
  port: 6379
  password: redis-pass

cache_params:
  ttl: 3600
  similarity_threshold: 0.85
Exact-match caching stores the full response under a key derived from model name, temperature, and exact prompt. For semantic caching, LiteLLM embeds the prompt using a configured embedding model (default text-embedding-3-small) and performs a vector similarity search in Redis. When similarity exceeds the threshold, the cached response is returned without hitting any LLM provider.
Trade-off analysis: exact caching guarantees correctness but has low hit rates on variable prompts. Semantic caching increases hit rate from 12% to 37% in customer support chatbots but introduces a small risk of returning a slightly off-topic answer. Disable semantic caching for math or code generation workloads where precision matters more than cost.
Cache keys can be scoped to a user or tenant ID by setting cache_key_prefix in the request metadata, preventing cross-tenant contamination.
Observability Integration Patterns
The proxy emits OpenTelemetry traces by default when OTEL_EXPORTER_OTLP_ENDPOINT is set. Each trace includes the virtual key hash (never the real key), model name, latency breakdown per provider, token counts, and spend. This data feeds into Prometheus for alerting.
A typical Prometheus scrape config targets the /metrics endpoint exposed on port 4000. Key metrics include:
litellm_request_totallabeled by model and statuslitellm_latency_secondshistogramlitellm_spend_totalcounterlitellm_cache_hit_total
For deeper debugging, forward logs to LangSmith, Helicone or Datadog by configuring a callback:
litellm.callbacks = ["langsmith", "prometheus"]
Helicone integration requires only an additional header Helicone-Auth: sk-helicone-xxx on incoming requests; the proxy forwards it automatically. This pattern gives per-request trace IDs that link proxy logs with application logs without changing client SDK code.
Pre-Call and Post-Call Hooks
Hooks allow custom logic before and after every LLM call. A common security pattern implements prompt guarding:
async def guard_prompt(data: dict):
    prompt = data["messages"][-1]["content"]
    if contains_pii(prompt):
        raise Exception("PII detected")
    return data

litellm.input_callback = [guard_prompt]
Post-call hooks can redact sensitive data from responses before they reach the client or write audit logs to an immutable store. Hooks run synchronously by default; mark them async when performing network calls to avoid blocking the event loop. The proxy uses asyncio to run multiple hooks in parallel when possible.
Worked Example: Customer Support Agent
Consider a multi-tenant support agent that routes customer questions to the cheapest model that meets quality thresholds. The config defines three model groups:
model_list:
  - model_name: support-fast
    litellm_params:
      model: groq/llama3-70b-8192
  - model_name: support-quality
    litellm_params:
      model: anthropic/claude-3-sonnet-20240229
  - model_name: embedding
    litellm_params:
      model: openai/text-embedding-3-small
Client code remains identical to the official OpenAI SDK:
from openai import OpenAI
client = OpenAI(
    base_url="http://localhost:4000",
    api_key="sk-virt-abc123"
)

response = client.chat.completions.create(
    model="support-fast",
    messages=[{"role": "user", "content": user_question}],
    temperature=0.2,
    metadata={"user_id": "cust_987"}
)
The proxy logs the spend against the virtual key tied to cust_987. If Groq returns rate-limit errors twice, the fallback configuration automatically retries with Claude. The embedding model is used internally for semantic cache lookup before any generation call. Total code change required to add this resilience and cost control: zero lines in the application.
Rate Limit Handling and Queuing
Each provider publishes different rate limits. LiteLLM maintains a token bucket per model and key combination. When a request would exceed the bucket, the proxy returns HTTP 429 with a retry-after header calculated from the bucket refill rate. For bursty traffic, enable the Redis queue mode:
general_settings:
  enable_pre_call_checks: true
  queue: true
Requests are pushed to a Redis queue and processed by background workers at the allowed rate. This smooths traffic spikes and prevents one noisy tenant from starving others. The trade-off is added end-to-end latency of up to 800 ms during peak hours, which must be weighed against the cost of over-provisioning API keys.
Deployment Architectures
Three common deployment patterns exist. The simplest is a single Docker container running the proxy connected to PostgreSQL and Redis. For larger scale, deploy the proxy as a Kubernetes Deployment with horizontal pod autoscaling based on CPU and queue depth. Each pod shares the same configuration via a ConfigMap.
For zero-downtime model updates, use blue-green deployments: spin up a new proxy fleet with updated config.yaml, shift traffic gradually using a service mesh, then decommission the old fleet. Because virtual keys are stored in the shared database, keys remain valid across deployments.
Edge deployment is possible by running LiteLLM on Cloudflare Workers or Fly.io Machines close to users. In this configuration, reduce Redis TTL to 300 seconds and accept lower cache hit rates in exchange for lower latency.
Security Considerations
The proxy never logs raw API keys. Virtual keys are hashed with SHA-256 before storage. When connecting to providers that require IP allow-listing, all proxy egress IPs must be added. Use mTLS between the proxy and internal services when operating in a zero-trust environment.
Input and output moderation hooks should run before caching to prevent storing harmful content. For GDPR-compliant deployments, configure the proxy to delete logs older than 30 days using the built-in retention settings in the database URL parameters.
Performance Overhead Measurements
Adding the proxy introduces roughly 18 ms of median latency in a same-region setup (measured between a Node.js client and proxy on the same VPC). Redis cache hits return in under 4 ms. The proxy itself handles 1800 requests per second on a single c6i.2xlarge instance before CPU saturation. These figures come from community benchmarks published in the LiteLLM GitHub discussions; actual numbers depend on hook complexity and network conditions.
Token usage remains identical to direct calls because the proxy forwards the exact parameters. Spend tracking adds negligible overhead as it uses batched database writes every 60 seconds.
Integration with Frameworks
LiteLLM proxy works seamlessly with LangChain, LlamaIndex, and Vercel AI SDK because it speaks the OpenAI protocol. For LangChain, simply set base_url to the proxy endpoint. When using LangGraph agents that make multiple tool calls, the proxy's per-key rate limiting prevents any single user from exhausting the entire organization's quota.
With Haystack or Semantic Kernel, configure the LLM component to point at the proxy URL and use the virtual key. The observability data emitted by the proxy can be correlated with framework-level traces using the trace_id passed in request metadata.
Cost Optimization Patterns
Three patterns deliver measurable savings. First, automatic model fallback from expensive to cheaper providers when confidence scores (extracted from response metadata) exceed a threshold. Second, aggressive caching of embedding vectors for retrieval-augmented generation; many customer queries repeat, yielding 40-60% cache hit rates after the first week. Third, scheduled jobs that analyze weekly spend per model and suggest config changes, such as moving stable workloads to provisioned throughput offerings on Azure or Bedrock.
Budget alerts configured in the proxy send Slack notifications when a key reaches 80% of its monthly limit. This early warning prevents surprise bills at the end of the month.
Common Pitfalls and Mitigations
Pitfall one: mismatched temperature or max_tokens between providers. LiteLLM normalizes some parameters but not all; explicitly map them in litellm_params using extra_headers or model-specific overrides.
Pitfall two: caching responses that contain user-specific data. Always include a cache_key_prefix derived from tenant ID or user hash.
Pitfall three: assuming all providers return identical error formats. The proxy normalizes most errors to OpenAI format, but certain streaming edge cases still differ. Test fallback behavior with chaos engineering tools that inject random 5xx responses.
Pitfall four: overly broad model fallback lists that route sensitive prompts to providers with weaker compliance. Maintain separate model groups for different data sensitivity tiers.
Monitoring Dashboard Recipe
Combine Prometheus, Grafana and the LiteLLM admin UI. The admin UI at /ui provides spend breakdowns per key, model and team. Grafana dashboards should display latency heatmaps by provider, cache hit ratio trends, and error rates with annotations for config changes. Set alerts for cache hit ratio dropping below 25% or error rate exceeding 2% on any model group. These signals indicate either changing query patterns or provider degradation.
The combination of centralized logging, metrics and the proxy admin UI reduces mean time to resolution for LLM-related incidents from hours to minutes.
When Not to Use the Proxy
Do not use the proxy for latency-critical paths under 100 ms, such as autocomplete or real-time translation, unless the proxy runs in the same process via the SDK rather than HTTP. For single-provider applications with no budget tracking or moderation needs, the added operational complexity may outweigh benefits. Finally, organizations subject to strict data residency rules must ensure the proxy and all fallback providers satisfy the same geographic constraints.
The patterns above represent battle-tested configurations observed across multiple production LLM platforms. Apply them incrementally: start with virtual keys and spend tracking, add caching, then introduce routing. Each layer adds resilience and cost control while maintaining a clean, provider-agnostic interface for application developers.